On October 17, DeepSeek released V4.1-Flash-1017, an update to V4.1-Flash The same day, the API’s deepseek-flash model and the web and app were switched to this version
It also released Search and Fetch APIs for its own search engine Search calls made through Claude Code and Codex are free until the end of October
 Demo of a 3D scene of the Forbidden City made by V4.1-Flash-1017 — Source: DeepSeek
What was announced
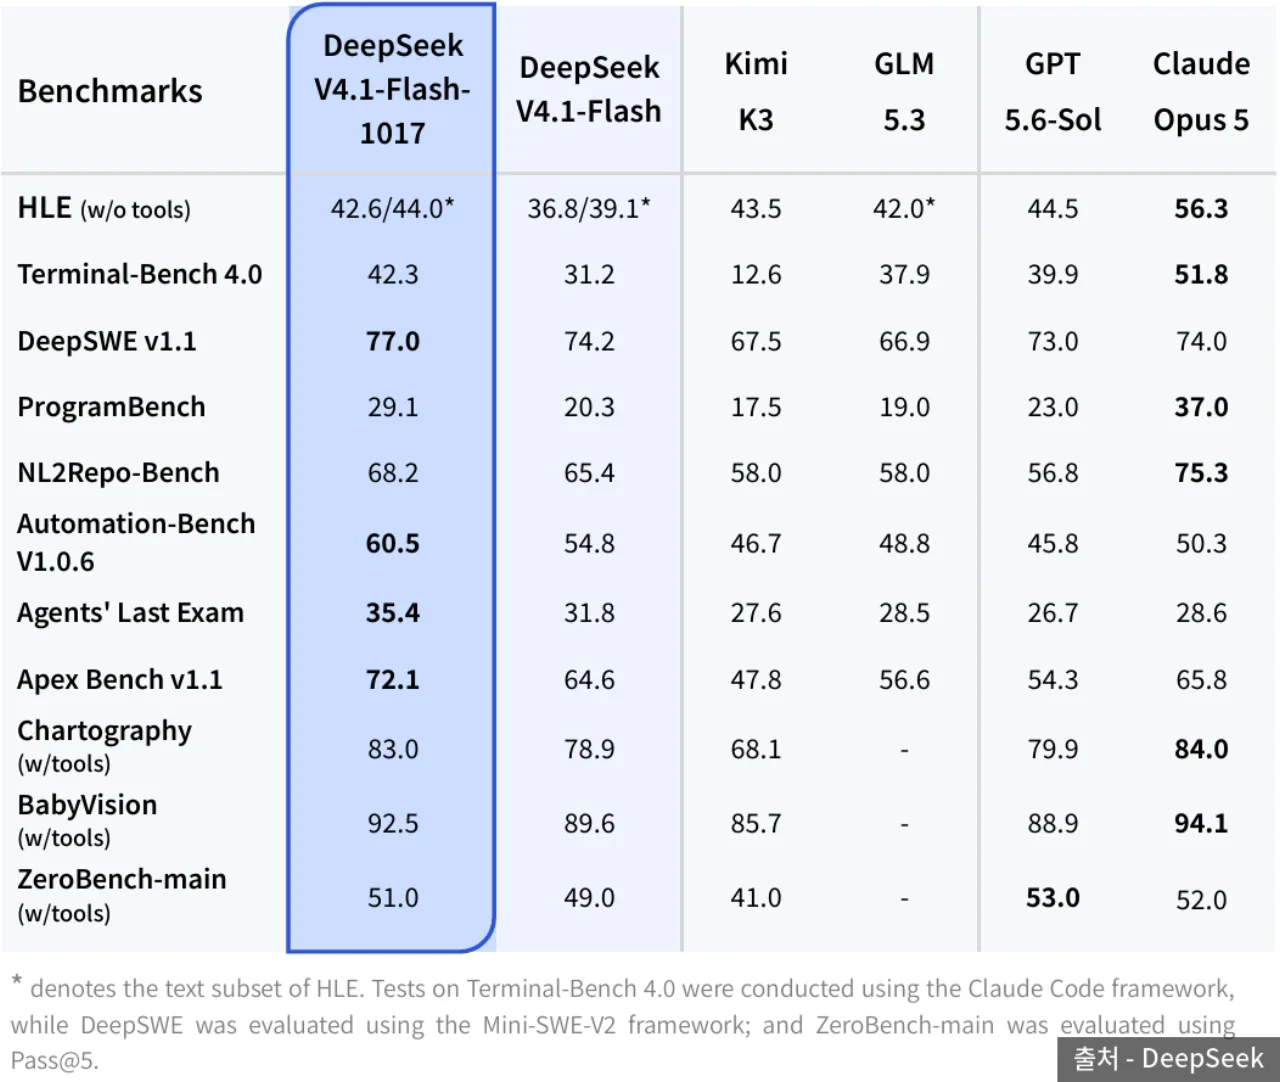 DeepSeek’s official benchmark table comparing the 1017 version with the previous version and competing models — Source: DeepSeek
DeepSeek introduced the 1017 version as a minor update to V4.1-Flash It says it raised reasoning, coding, and agent scores while cutting task time and output length
- Weights: released on Hugging Face and ModelScope, MIT license
- Size: 763B total parameters
- Context: 1 million tokens, up to 384K output tokens
- Input: text and images
- API: requests under the old name deepseek-v4-flash are also served by 1017
As examples, it showed 3D modeling of the Forbidden City, a web racing game, and a 3D scene running from prehistory to the present
Benchmark numbers
In DeepSeek’s own measurements, the biggest gain was on Terminal-Bench 4.0 It rose from 31.2 to 42.3, up 11.1 points!
| Benchmark | Previous V4.1-Flash | 1017 |
|---|---|---|
| HLE (no tools) | 36.8 | 42.6 |
| Terminal-Bench 4.0 | 31.2 | 42.3 |
| DeepSWE v1.1 | 74.2 | 77.0 |
| ProgramBench | 20.3 | 29.1 |
| Automation-Bench | 54.8 | 60.5 |
The table compares against Claude Opus 5 and GPT 5.6-Sol Claude Opus 5.5 and Sonnet 5.5, released in September, and the GPT-6 family are not in this table
Even in the same table, Opus 5 scores higher on HLE, Terminal-Bench, and ProgramBench A footnote says Terminal-Bench was measured in the Claude Code environment
Scores for the 1017 version from outside evaluators such as Artificial Analysis are not out yet
Cost per task
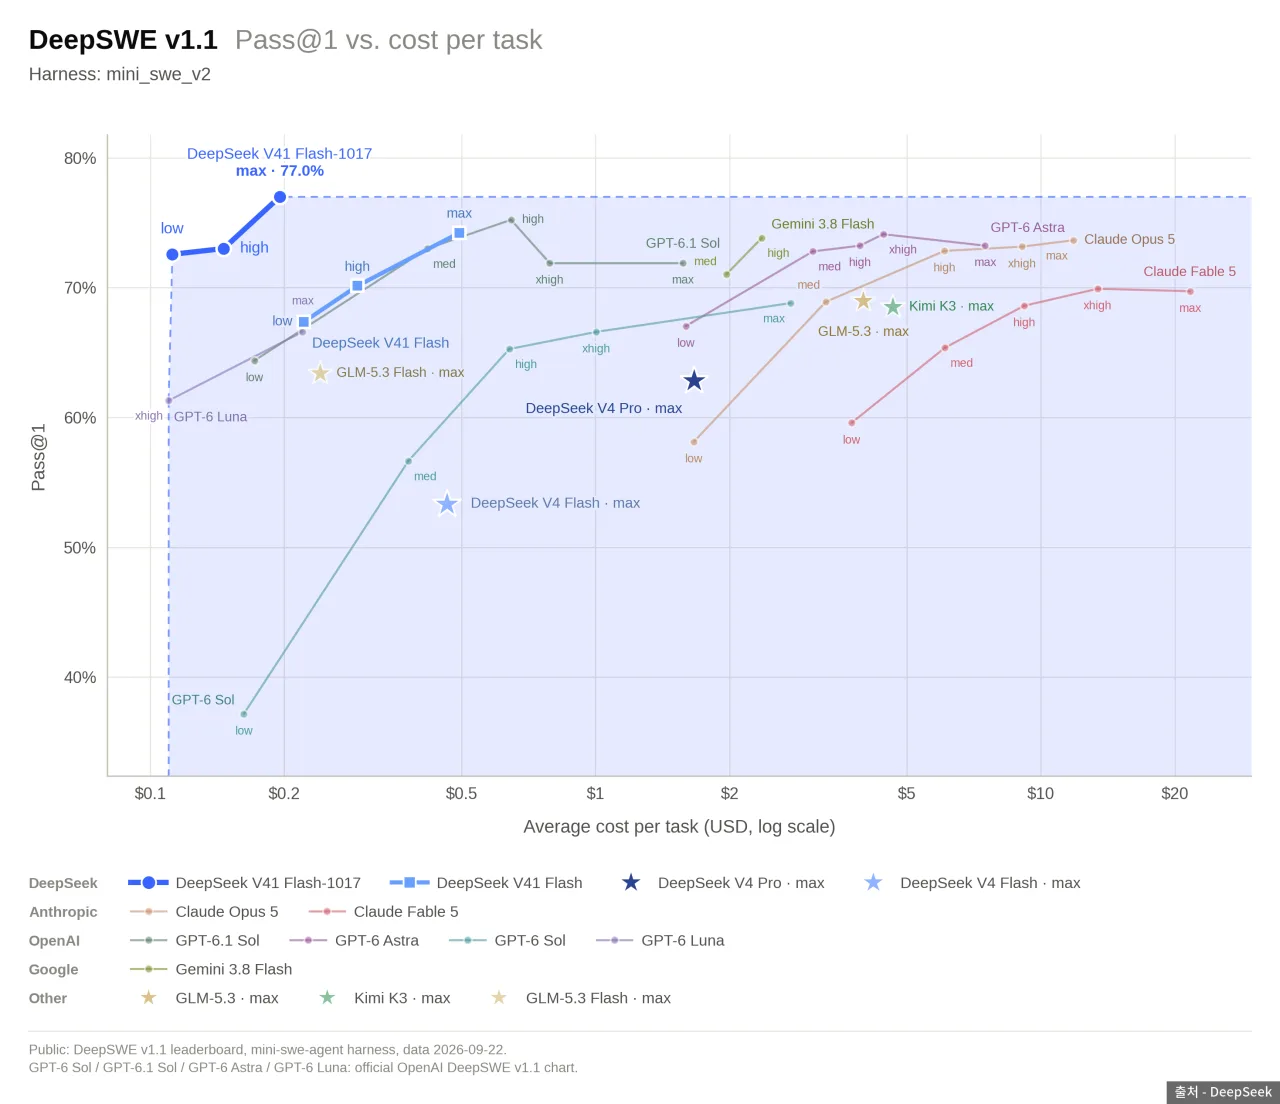 Chart of DeepSWE v1.1 accuracy versus average cost per task — Source: DeepSeek
It shows 77.0% accuracy on DeepSWE v1.1 at about $0.2 (₩280) per task
On the same chart, GPT-6.1 Sol max is around 72% at about $1.6 (₩2,200) Claude Opus 5 max is shown at about 74% for around $12 (₩16,000)
The chart figures were produced by DeepSeek, and the won amounts are approximations converted by reading the axis DeepSeek's explanation is that shorter output, more than the per-token price, lowered the cost per task
Pricing and Korean business hours
 DeepSeek logo
deepseek-flash pricing differs by a factor of two depending on the time of day Peak hours are 01:00–04:00 and 06:00–10:00 UTC on weekdays
In Korean time, that is 10 a.m.–1 p.m. and 3 p.m.–7 p.m. on weekdays!! Peak pricing applies to most of the Korean workday
| Per 1M tokens (₩) | Peak | Other times |
|---|---|---|
| Input (cache hit) | 8.4 | 4.2 |
| Input (cache miss) | 420 | 210 |
| Output | 1,680 | 840 |
Claude Haiku 5.5’s list price is ₩140 for input and ₩700 for output per 1 million tokens Looking only at per-token prices, even DeepSeek’s off-peak rate is higher than Haiku 5.5
Cost per task depends on how many tokens are used, so you can’t conclude which is cheaper from unit prices alone
The search API and connecting Claude Code
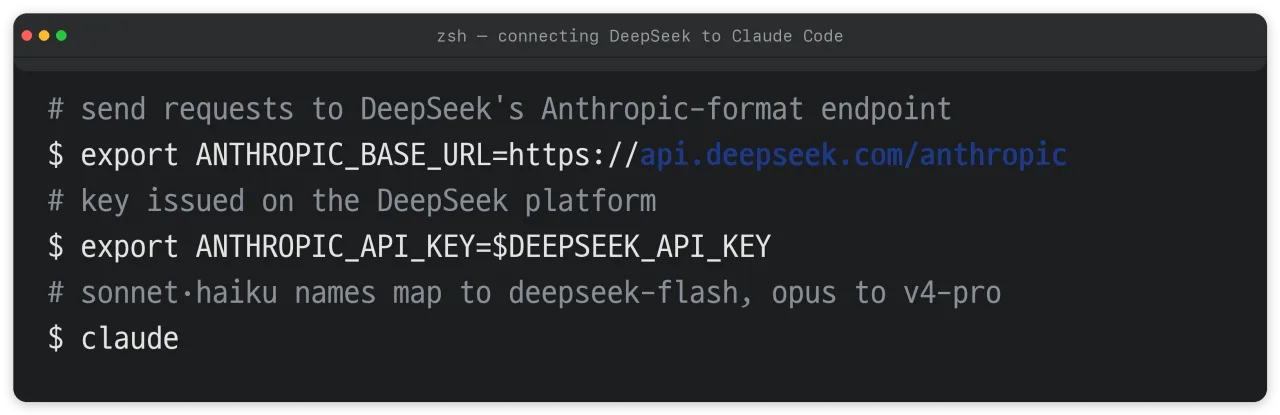 Environment variable settings that connect Claude Code to the DeepSeek API — Source: self-rendered based on DeepSeek API documentation
The Search API returns a list of search results
The Fetch API returns a single web page as Markdown body text
Both cost $0.75 (₩1,050) per 1,000 successful requests
Searches that DeepSeek Harness, Claude Code, and Codex call as server-side tools are currently free Billing starts at 1 a.m. Korean time on November 1
Claude Code connects through DeepSeek’s Anthropic-format endpoint In that case, Claude model names are handled as DeepSeek models
DeepSeek says it ignores fields such as mcp_servers and cache_control Some Claude Code features may not work as is
What to check when using it in Korea
 Personal Information Protection Commission logo
In April 2025, the Personal Information Protection Commission issued a corrective recommendation to DeepSeek An inspection confirmed that user prompts had been sent to a ByteDance affiliate without consent
DeepSeek stopped offering new app downloads in Korea on February 15, 2025 It resumed on April 28 after publishing a Korean privacy policy
Around the same time, government ministries such as the Ministry of Foreign Affairs and the Ministry of National Defense, as well as the financial sector, blocked access to DeepSeek on their work networks
Code and documents sent through the API are processed on DeepSeek’s servers If you handle company code or customer information, check your internal security rules first
If you download the weights and run them yourself, nothing is sent outside But even by simple calculation at 1-byte precision, 763B means the weights alone are about 763GB, which is hard on a personal PC
What to watch next
- End of free search API: 1 a.m. Korean time, November 1
- Outside evaluations: scores for the 1017 version from Artificial Analysis and others
- Higher-tier model: deepseek-v4-pro is still on the 0813 version
- Korean regulation: whether the PIPC follows up with another inspection
Sources
- [DeepSeek] DeepSeek-V4.1-Flash-1017 release notice (2026-10-17)
- [DeepSeek] Models and pricing (peak hours, Search and Fetch pricing)
- [DeepSeek] Search and Fetch API documentation (call limits, start of billing)
- [DeepSeek] Anthropic API compatibility documentation (Claude Code setup, ignored fields)
- [Hugging Face] DeepSeek-V4.1-Flash-1017 model card (license, parameters)
- [Anthropic] Claude Haiku 5.5 pricing (comparison baseline)
- [News Tomato] PIPC issues corrective recommendation to DeepSeek (2025-04-24)
- [Aju Business Daily] DeepSeek resumes service in Korea (2025-04-28)
- [Seoul Economic Daily] Government, banks, and brokerages ban DeepSeek (2025-02)
- Exchange rate: converted at $1 ≈ ₩1,400